About Redpine
Redpine is a licensed knowledge layer that gives AI builders and autonomous agents compliant access to premium, non-public data.
What Redpine does
AI is only as good as the data it is grounded in. Where the open web plateaus, Redpine begins. We license directly with copyright holders, publishers, and proprietary dataset owners, then make that data usable by agents through API, MCP, and CLI.
Licensed access for AI agents
Redpine is a grounding layer for data that does not exist in any public crawl. AI builders and agents query the platform through API, Model Context Protocol (MCP), and CLI, and receive licensed context instead of scraped web text.
Agents can reason over scientific, medical, legal, financial, and other specialist sources without assembling those datasets themselves.
Direct licensing with content owners
We sign licensing agreements with publishers, copyright holders, research firms, and proprietary data owners before any data moves. Contracts first, access second. No gray zones.
That produces commercially usable data for AI companies, and a recurring revenue path for the people who created the underlying knowledge.
AI-ready retrieval, not a file dump
Licensed data on Redpine is stored with provenance, structured metadata, and formats agents can consume. A proprietary retrieval and reranking stack, led by founding data scientist Dr. Leonora Vesterbacka, evaluates relevance and quality at query time.
Builders get licensed passages at query time, without standing up their own licensing desk.
Reinforcement Learning
Redpine builds reinforcement learning gyms from proprietary data that frontier models have never seen, so that labs can train their models on a wide range of real-world tasks where every attempt produces a clear and verifiable learning signal.
Monetization for data owners
Content owners keep control. They license specific corpora for AI use and receive a revenue share when agents consume that data. Usage is metered. Attribution stays attached to the source.
This is the same pattern David Österdahl saw work in music: licensed access replaced a piracy economy because it was easier to use, and because rights holders got paid.
What makes Redpine different
We do not scrape. We partner.
Licensed at the source, not taken from the crawl
Most AI systems still lean on open-web text and scraping vendors. That corpus is the familiar 1% of the world’s data, and it is legally fraught in the domains that matter.
Redpine starts with a contract. Data enters the platform only after the rights holder has opted in. That is a different starting point from crawl products and from any pipeline that treats Common Crawl as good enough for medicine, law, or finance.
An access layer for agents, not an annotation factory
Annotation platforms are built around human labeling workflows. They produce static, annotated datasets. That is a real category. It is not what Redpine sells.
Redpine is API-native. Agents query live licensed sources through MCP, REST, and CLI. Quality is evaluated at retrieval time. The unit of work is a query, not a labeling project.
Pay for what the agent uses
Enterprise data deals often arrive as a mandated 12-month contract and a file drop. Redpine bills AI builders on usage, typically per token consumed, and every account starts with 5 free queries.
Cost follows consumption. A prototype does not require an annual seat. A production agent pays for the context it actually reads.
Built for work where “almost right” fails
Redpine concentrates on medicine, science, law, and finance, plus other fields where hallucinations are unacceptable. Source attribution travels with the data. Retrieval is designed to prefer the right passage over the nearest embedding.
Data brokers sell archives. Search indexes sell the public web. Redpine sells grounded, licensed context for systems that have to be correct.
Incentives that point the same way
Builders get compliant data without standing up a licensing desk. Owners get paid when their knowledge is used. That two-sided structure is the point of the company.
Traditional brokers extract and resell. Scrapers do not pay the source. Redpine’s commercial model only works if both sides stay in the market.
Who uses Redpine
Redpine sits between two groups that rarely share a vendor: the teams building AI systems, and the institutions that own the knowledge those systems need.
- Foundation model labs and AI platform teams that need licensed data for training, fine-tuning, and inference.
- Applied AI and agent teams at product companies who want MCP or API grounding instead of assembling datasets in-house.
- Healthcare, life-science, and biotech builders working with clinical, scientific, and research content. AsedaSciences is a named public example.
- Publishers, copyright holders, research firms, and proprietary data owners who want controlled AI access and a usage-based revenue share.
The founders of Redpine
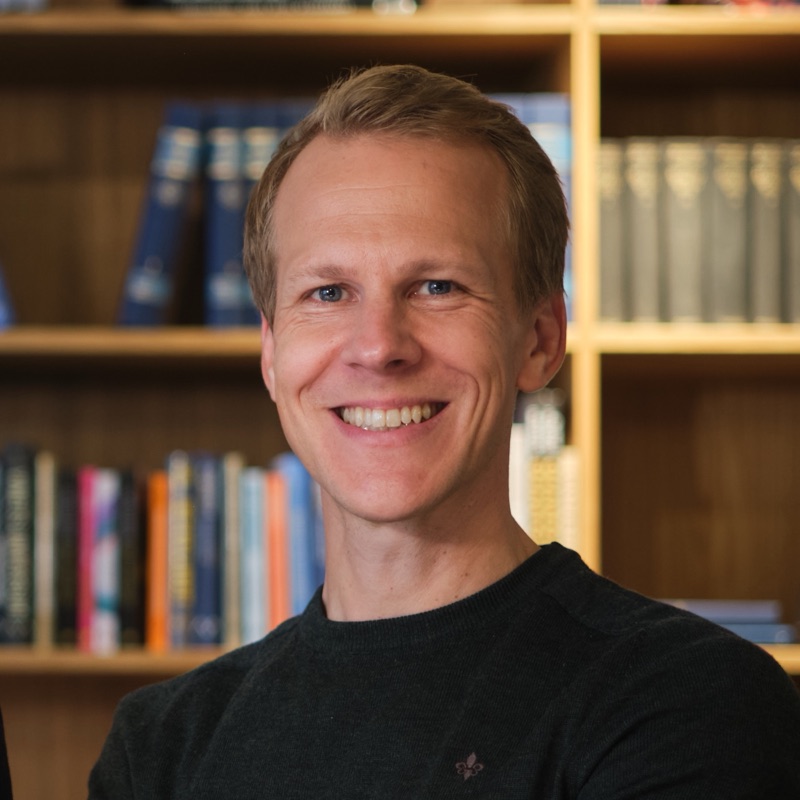
CEO and co-founder
Anders Hammarbäck
Anders previously worked at McKinsey and was a partner at Antler, including leading Antler in the Nordics. He started Redpine after watching AI companies train on the same scraped sources, with no moat and no payment to rights holders.
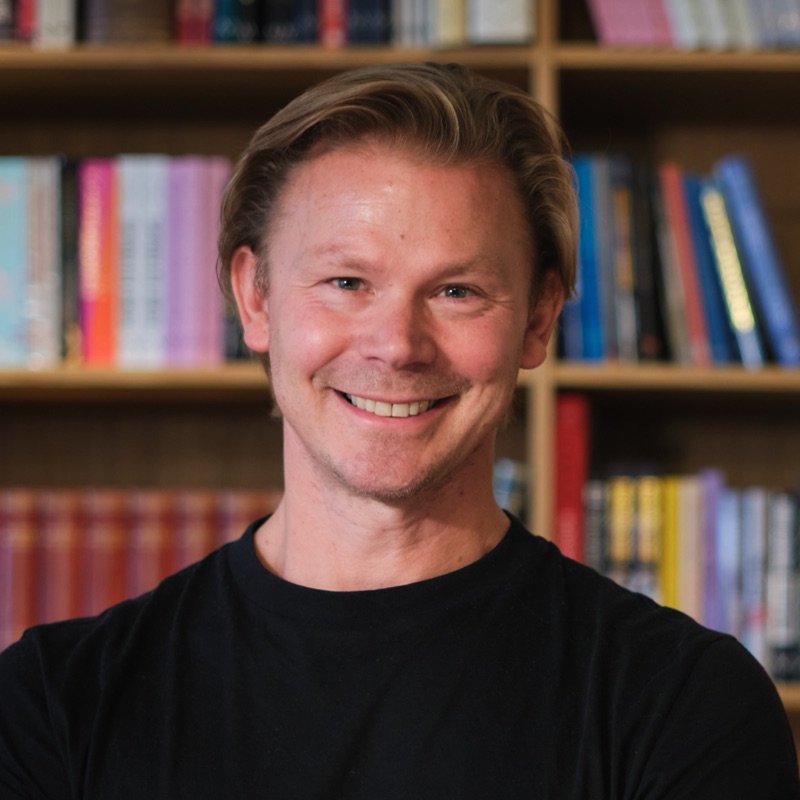
CPTO and co-founder
David Österdahl
David was part of the early product and technology team at Spotify, then held product and tech roles at Zettle and Lunar. He treats AI data the way Spotify treated music: licensed access has to be easier than piracy, or it will not replace it.
Origin
Founded in Stockholm, 2024
Anders and David founded Redpine in Stockholm in 2024. After a year in stealth, it launched publicly in 2025. The wider team brings experience from four Nordic tech unicorns (Spotify, Sana, Zettle, Lunar) plus McKinsey, CERN, and H&M.
In April 2026 the company raised an $8M seed led by NordicNinja, with Luminar Ventures and node.vc. Strategic angels include Peter Sarlin (Silo AI), Patrik Tran (Validio), Anna Nordell Westling (Sana), and operators from OpenAI, Perplexity, and Spotify. NordicNinja general partner Marek Kiisa joined the board.
How Redpine works
Rights first
Every dataset on the platform starts with a direct license. Redpine does not move data, embed it, or serve it until the content owner has agreed the terms. Owners keep control over what is in scope.
Make the data AI-ready
Sources are stored with provenance, structured metadata, and formats agents can query. Retrieval and reranking run at request time so the agent receives the relevant licensed passage, not a raw archive.
Connect in under a minute
Simply paste a prompt into your agent of choice to get started. Builders can add the Redpine MCP server at https://api.redpine.ai/mcp, call the API, or use the CLI.
Query, ground, pay for use
The agent asks a question. Redpine returns licensed context. The builder pays for usage, typically by tokens consumed. The content owner receives a revenue share. Quality evaluation happens on the way through.
Key facts
Frequently asked questions
What is Redpine, and what does it actually do?
Redpine is a data platform for agentic AI: a grounding API for non-public data. We source premium data from content partners and make it accessible to AI builders and agents in a licensed, structured way.
Where the open web plateaus, Redpine begins.
How is Redpine different from a data broker or web scraping service?
We do not scrape. We partner. Redpine builds direct licensing relationships with content owners, so high-quality data can move into AI systems with aligned incentives.
We also build the access layer those systems actually use: API, MCP, and CLI. That is not what a broker selling a static dump does.
What types of data does Redpine offer?
Scientific and journal text from publishers. Real-time signal data. Non-public image libraries. Video assets for world models. Private code repositories. Spoken media, including All Ears.
The common thread is data that does not exist in a public crawl, from sources that chose to work with us directly.
How does Redpine keep data licensed and compliant for AI use?
By going to the source. Redpine signs licensing agreements with content owners before any data moves. No assumptions, no gray zones.
Provenance and attribution stay attached so systems in healthcare, finance, and law can show where an answer came from.
Who are the typical clients?
AI builders who treat data quality as the primary constraint, not a cleanup step. They come to Redpine to skip the legal complexity, sourcing work, and infrastructure of assembling premium datasets themselves.
On the supply side: publishers, research firms, and owners of proprietary archives that are valuable and underused for AI.
What does “AI-ready” mean here?
Two things. Legally ready: licenses signed, provenance documented, compliance checked. Technically ready: accessible formats, metadata, vectorization, and retrieval so an agent can consume the data without a preprocessing project.
What is the business model?
AI builders pay for usage. Content partners receive a revenue share. Every account starts with 5 free queries. Production access is metered rather than sold as a one-off archive.
Where is Redpine based, and why the name?
Redpine is headquartered in Stockholm, Sweden, and was founded in 2024. The red pine is one of the most elegant trees in Nordic forests. It also grows across North America and Asia.
Its longevity comes from deep roots. The AI ecosystem will thrive only if we nurture the roots properly: by compensating content and data owners. The name Redpine felt right.