Better Answers, Sharper Retrieval: Redpine Science Evaluated
Better Answers, Sharper Retrieval: Redpine Science Evaluated
Redpine Science gives models and agents a single access point to a wide range of peer-reviewed literature, queried directly through MCP and API. We set out to measure how much this access improves the answers models give. Many evaluations of a retrieval-augmented system report a single blended score: how well did the agent answer? That conflates two different effects: whether the system found the right information and whether the model wrote a good answer from it. A high score can come from either one, and the number alone can’t tell you which. We built evaluations that test the two separately.
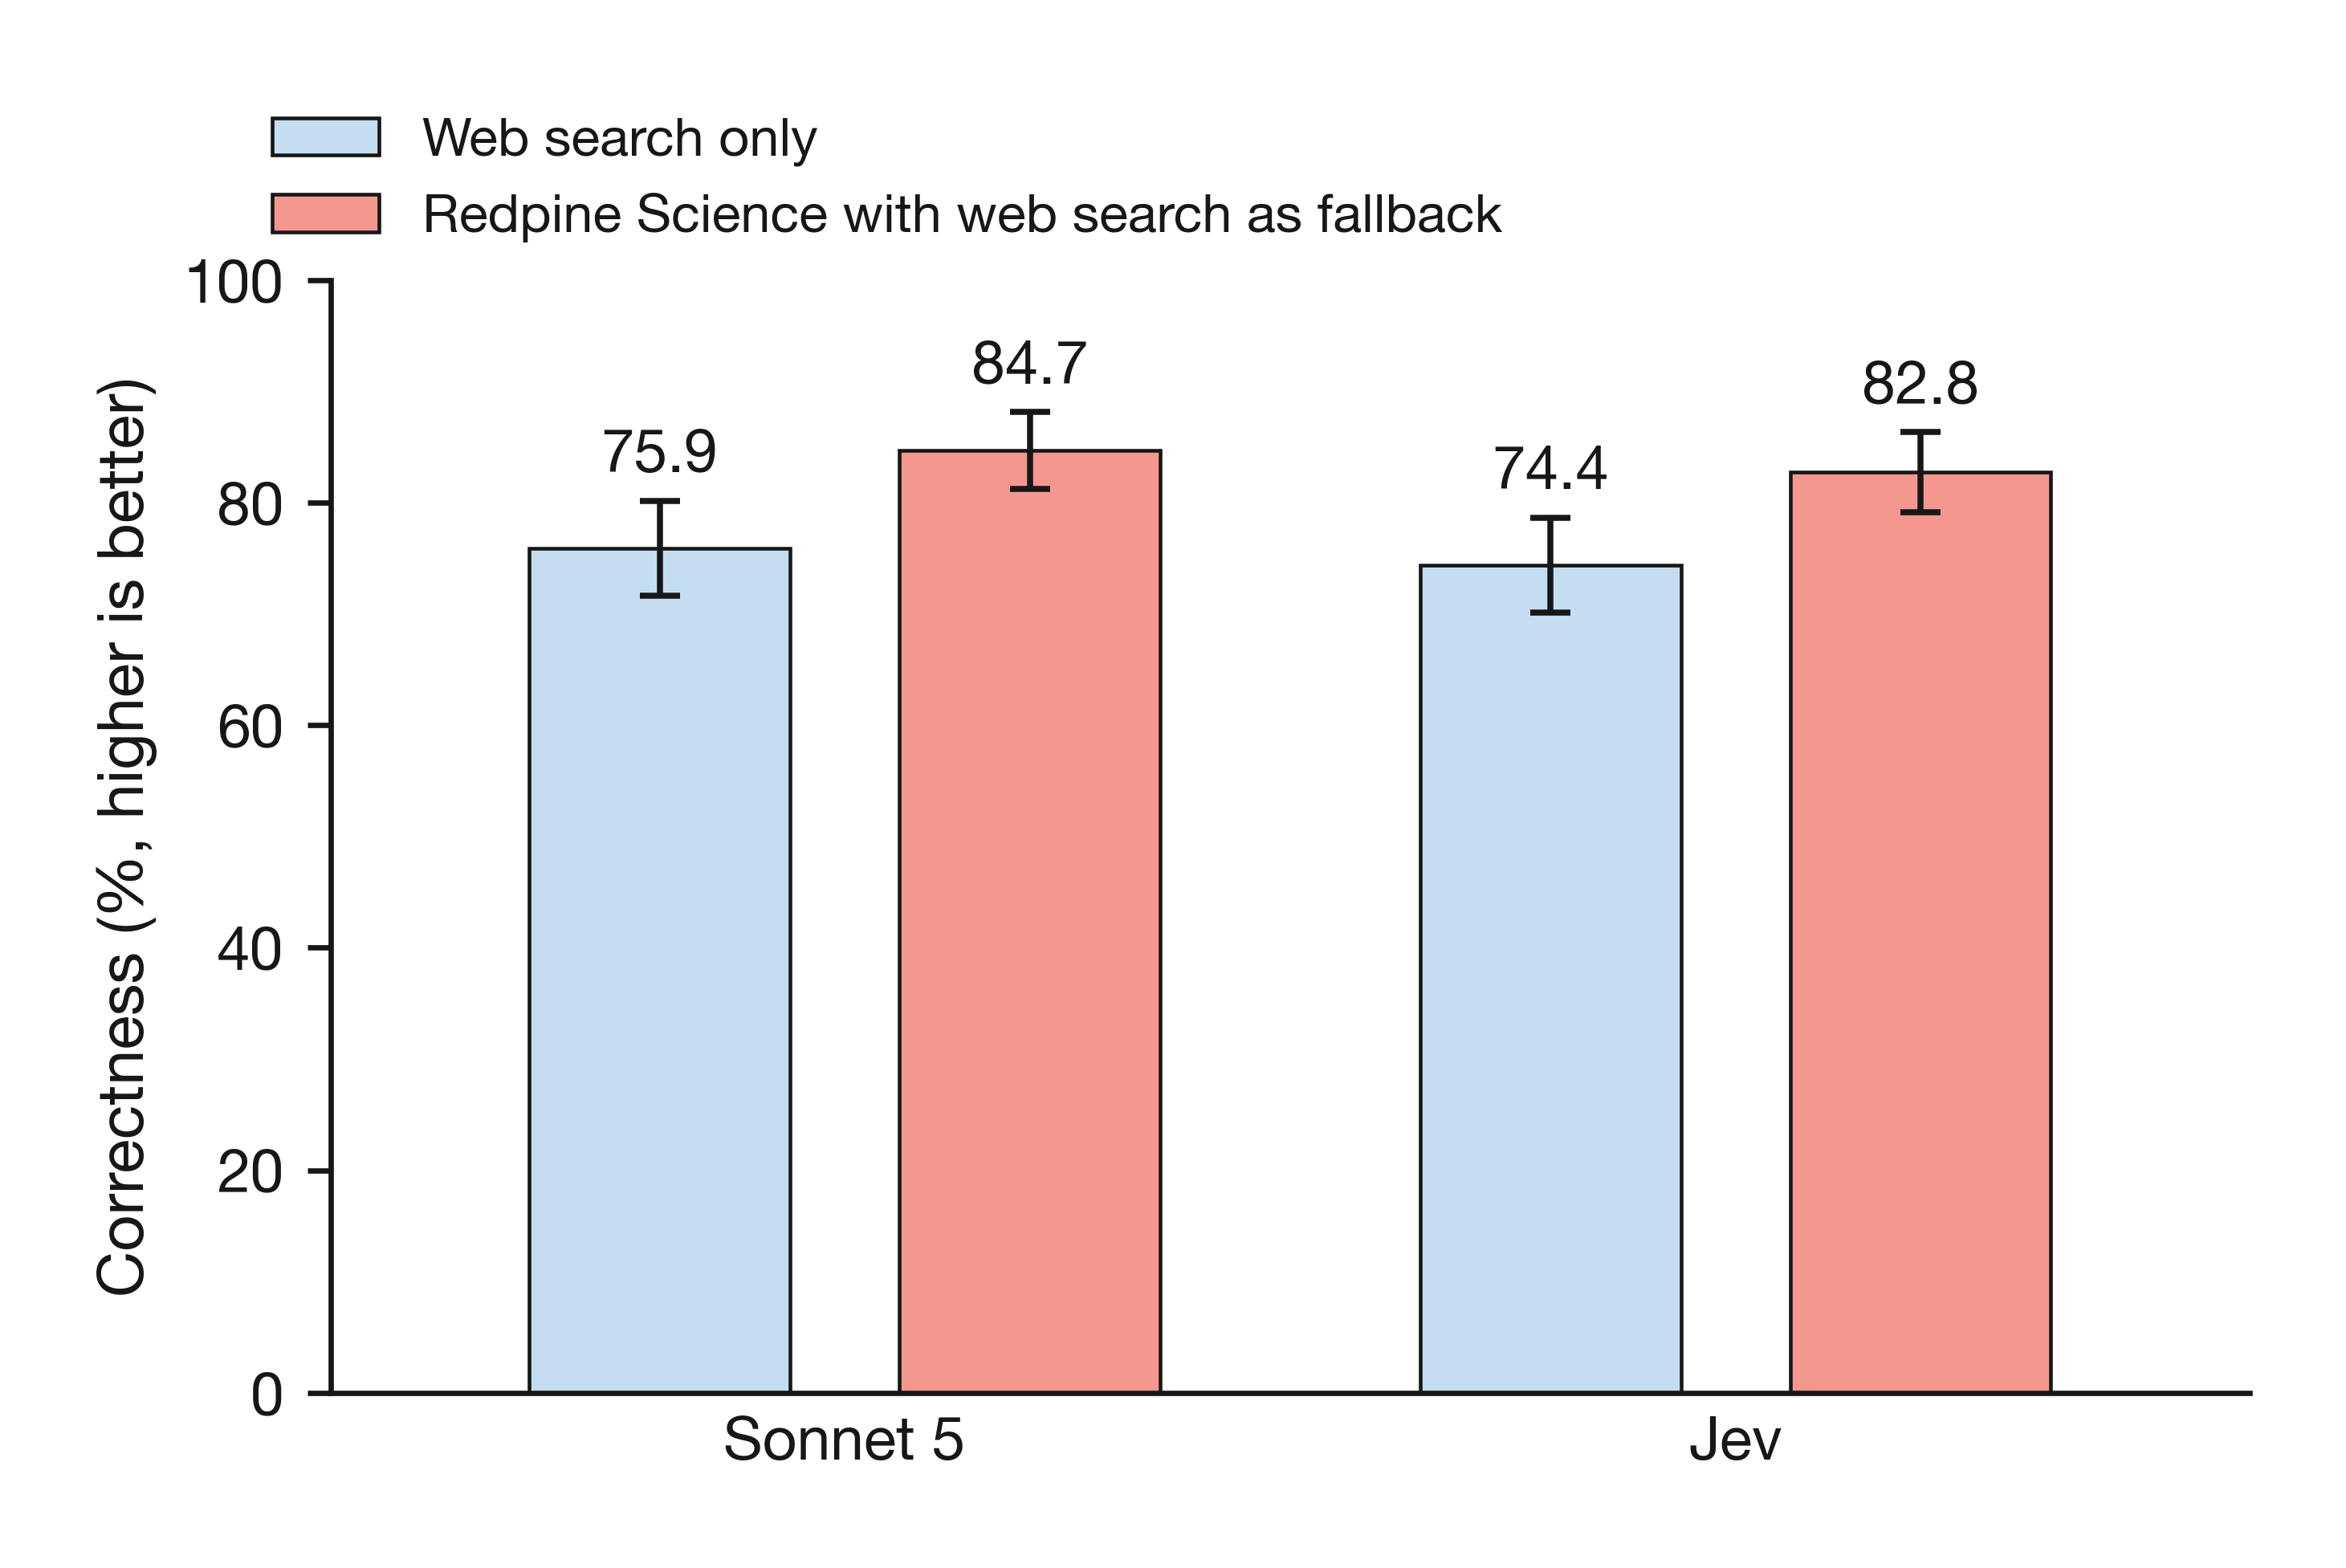
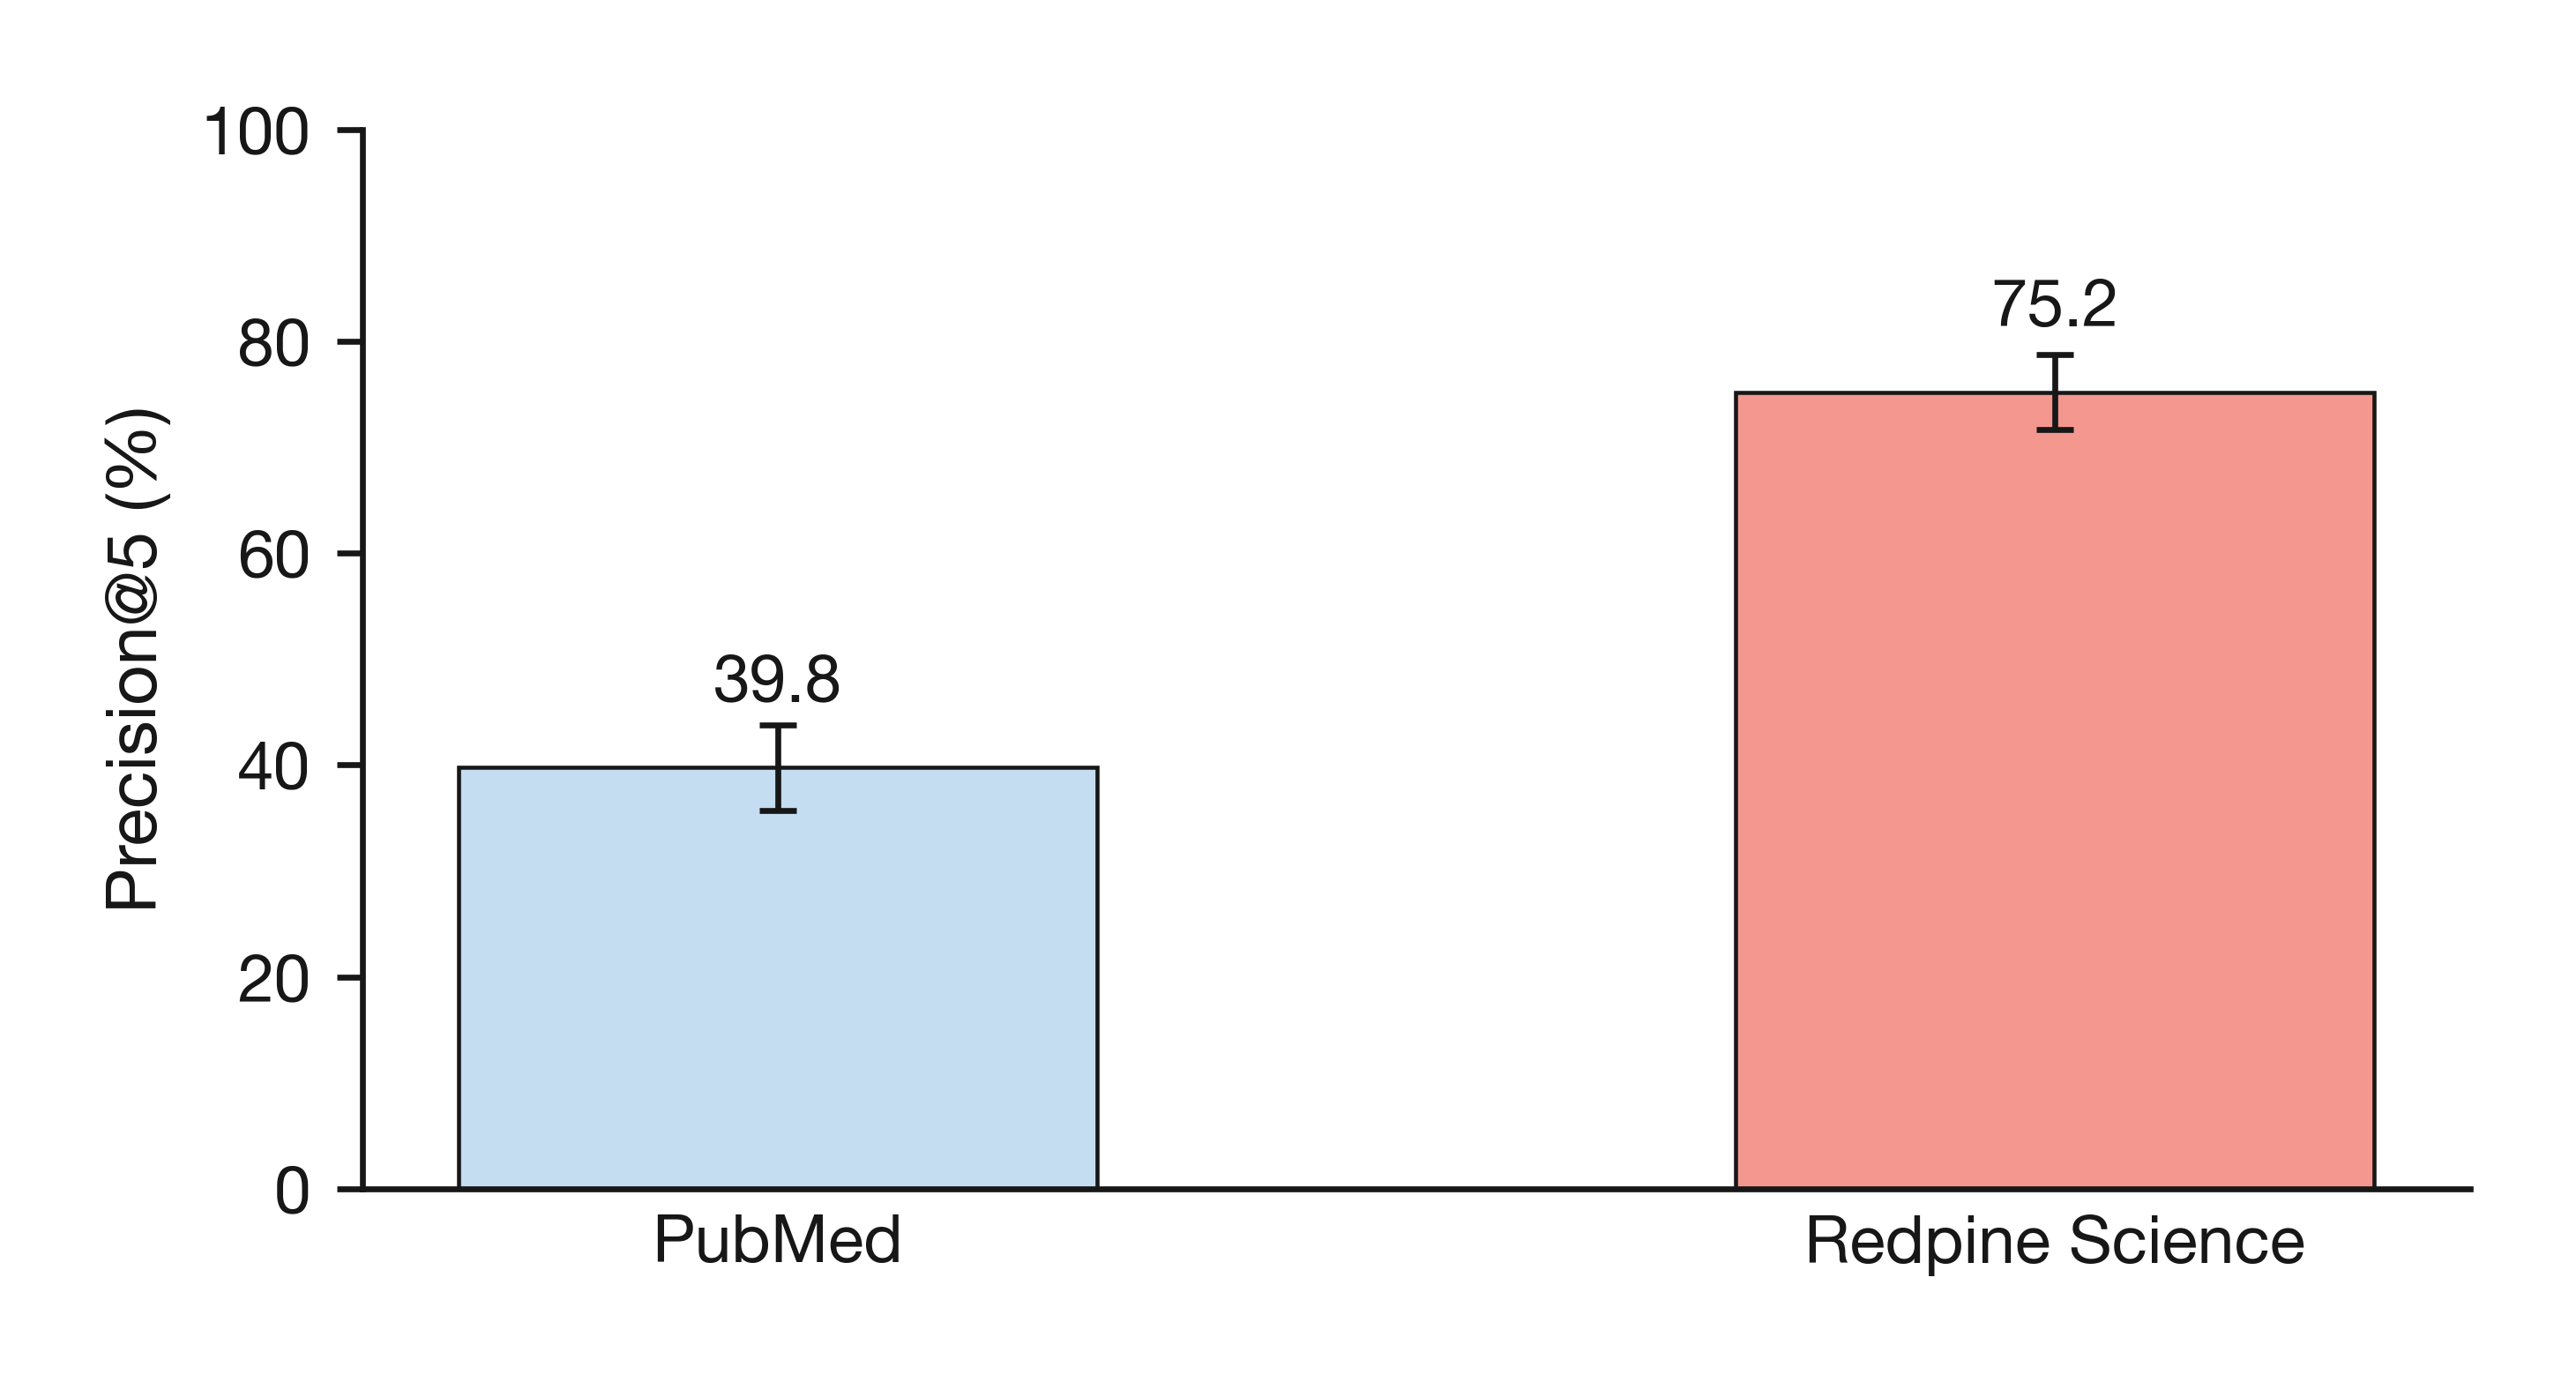
For answer quality, adding Redpine Science to web search raises the correctness of the agent’s answers from 75.9% to 84.7%. For retrieval, a blinded panel of domain experts (they didn’t know which system produced each result) rates Redpine Science’s top five results useful 75.2% of the time, compared with 39.8% for PubMed search.
In total we built and ran four such eval suites, all documented in the preprint and the benchmark repository.
Answer quality, on questions a model can’t just recall
Public benchmarks are useful because they’re comparable across labs and models, but they saturate: once enough of a benchmark can be answered from memory, a high score stops telling you whether retrieval helped at all. So we built our own biomedical benchmark of 179 questions, on findings recent enough that a model is unlikely to have seen them during training. Every question and its answer key was reviewed by a PhD-level domain expert before use.
An agent answers each question twice, once with web search alone and once with web search plus Redpine Science, as a real user would. A second model, the judge, then grades both answers against the key claims each answer should make: how many it states, how many it contradicts, and a combined correctness score. Under two different judges, correctness comes out higher with Redpine Science: 84.7% against 75.9% under the primary judge, 82.8% against 74.4% under a second judge used as a cross-check.
Three domain experts then labeled a blinded sample of the answers: on average, the judges agree with the experts about as well as the experts agree with one another (a standard agreement score, κ, of 0.59 versus 0.48), and the experts’ labels show the same direction of improvement as the judges’.
Retrieval accuracy, judged by domain experts
The evaluation above still mixes two things: what the system retrieved and how well the model wrote an answer from it. This evaluation isolates just the first half, judged by a blinded panel of domain experts who score every result directly for relevance.
On 115 questions, Redpine Science’s top five results are rated useful nearly twice as often as those from PubMed search, the tool many researchers use today to find biomedical papers. Results are also ranked better on average: mean DCG@5, which weights a relevant result more heavily the higher it’s ranked, is about 80% higher (7.26 against 4.02).
We also ran evaluations on public benchmarks, for both question answering and retrieval (including Exa’s publication-retrieval benchmark); those results are in the preprint. Everything behind these numbers is open: the 179-question expert-validated set and its answer keys, the 115-question relevance panel and its anonymized ratings, and the code that ran both evaluations. All of it is in the benchmark repository.
Check the data, rerun the evaluations, or try Redpine Science for yourself.